The situation
BUGECE ran everything on one physical server, applications and databases together. At peaks such as promotional campaigns and busy transaction hours the platform slowed down or went offline, which hurt customers and held back growth.
Images were the slowest part, and slow pages cost conversions. The payment system had bottlenecks of its own and some checkouts failed. With little monitoring, the operations team found problems late, and releases were manual and awkward to roll back.
What we did
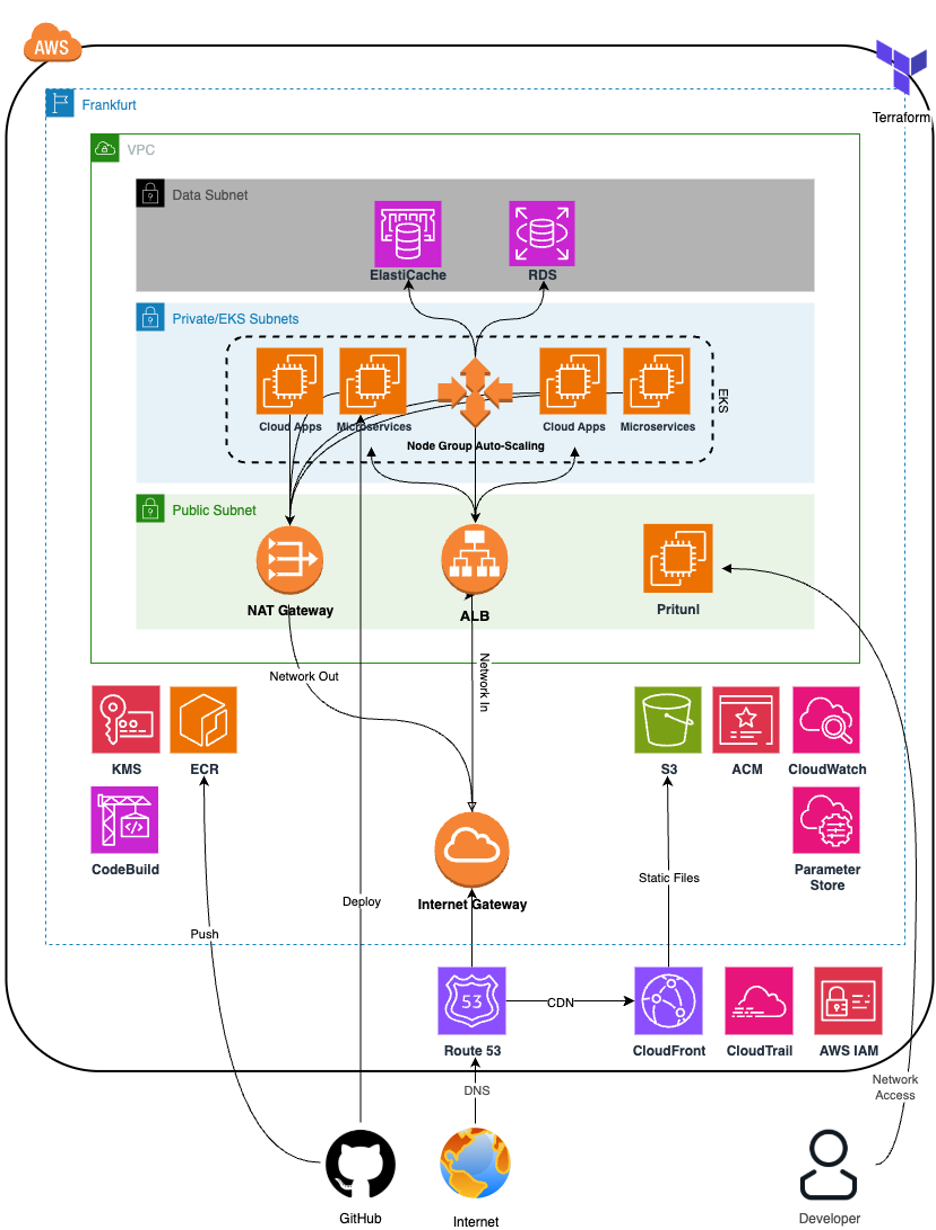
We moved the platform to AWS and started with the biggest problem, the images. Static files such as images, scripts and stylesheets now come from CloudFront edge locations instead of the origin servers, and we set CloudFront up to cache some dynamic pages too, including payment-related ones, which shortened the checkout. The applications run in containers on Amazon EKS, and deployments are automated with rolling updates, so releases are faster and cause less downtime.
Results
Delivery of images and static assets became over 60% faster. With dynamic pages cached by CloudFront and the backend tuned with Aurora and Redis, application response times improved by 40%. The origin servers are under less load, so the platform stays available during peaks. Monitoring shows the operations team what is happening and lets them react before users notice.
Under the hood
The network is a VPC with public, private and database subnets. The rest of the architecture:
- Amazon Aurora PostgreSQL for the database
- Amazon ElastiCache for Redis for fast access to data
- An Elastic Load Balancer in front of the EKS pods
- Horizontal pod autoscaling and cluster autoscaling
- Prometheus, Grafana and Amazon CloudWatch for monitoring
- Amazon ECR and rolling updates for deployments without downtime
- AWS KMS for encryption keys, and AWS Trusted Advisor for security and cost checks